Percentile ranks and deciles: how screens compare stocks
A percentile rank tells you where one stock sits relative to the other stocks in the same screening universe. A decile puts that rank into one of ten equal groups. A stock in the top decile on return on capital is among the strongest tenth of the names that could be ranked in that run.
Ranks are useful because they adapt when the market changes, but they always produce a winner. Even a weak field has a top decile. Pair relative ranks with absolute requirements when the thesis needs a minimum level of profitability or liquidity, and treat the universe definition as part of the calculation.
This builds on taking return measures apart and choosing a screening universe. Change the guest list and every relative position can change with it.
What does a percentile rank actually mean?
Suppose you line up every company with a valid return-on-capital figure from worst to best. Percentile rank is the company's position in that ordered set, expressed from the bottom to the top. In Quantery, pct_rank() runs from 0 at the minimum to 1 at the maximum. A value at or above 0.90 falls in the top decile under a simple cutoff.
Decile just means one tenth of an ordered population. Researchers use decile portfolios because a long list is hard to inspect, while ten buckets make the spread from low to high visible. The Kenneth R. French Data Library publishes portfolios sorted on size, book-to-market, operating profitability and investment. Its book-to-market construction offers broad groupings alongside quintiles and deciles, formed at the end of each June using NYSE breakpoints (portfolio construction details).
That last detail matters. The securities in the portfolios include NYSE, AMEX and Nasdaq stocks with the required data, while the cut points come from NYSE firms. A rank needs both a population to rank and a rule for where its buckets begin. Those choices aren't plumbing. They define what "top" means.
Ties and missing values need rules too. Quantery gives tied observations the same rank. A null, which means the feature couldn't be calculated, stays null and leaves the ranking denominator. It doesn't become a bad value or earn a place in the bottom bucket. If unusual filers lack the inputs your feature needs, the effective ranking universe is smaller than the universe block suggests.
Why do relative ranks adapt to the market?
An absolute test asks whether a company clears a fixed bar:
roc >= 0.15A relative test asks whether the company ranks above most peers:
roc_rank >= 0.90The fixed bar keeps its economic meaning from one run to the next. The rank keeps its competitive meaning. If returns on capital fall across the market, fewer companies may clear the fixed bar, perhaps none. The rank still identifies the leaders of the diminished field. When profitability is broadly strong, the fixed rule may admit many names while the rank keeps selecting the upper tail.
Neither behavior is a defect. If your claim is "exceptional profitability compared with other available businesses," a rank fits. If it is "the operation must earn enough to cover a real hurdle," you need an absolute threshold. Some theses need both.
Ranks also help when two metrics live on different scales. Earnings yield measures operating earnings against enterprise value. Return on capital measures those earnings against capital employed. Adding the raw ratios would let whichever one has the wider numerical spread dominate. Converting each to a percentile puts both on the same relative scale before combining them.
There is a price for that convenience. A rank discards the size of the gap between observations. The best and second-best companies may be far apart or nearly tied, yet their positions remain adjacent. Two companies sitting around a bucket boundary can have almost identical economics and different labels. Read the raw feature beside the rank. The rank sorts; it doesn't explain the distance.
The universe sets every rank
A company's accounting figure belongs to that company. Its percentile rank belongs to the whole run.
Remove banks, utilities and property companies, and the distribution of return on capital changes. Raise the market-cap floor and small firms disappear. Require complete filing data and recent listings may drop out. The remaining companies all move relative to one another even though none of their filings changed.
This is why copying a "top decile" rule without copying its universe doesn't reproduce a method. A top-decile industrial company among large US listings may sit elsewhere in an all-sector small-cap universe. The French library's use of NYSE breakpoints is a concrete example of controlling which firms set the boundaries instead of letting the smallest listings crowd the buckets.
Quantery's pct_rank(feature_name) uses the scan universe after sector exclusions, and only non-null values of that feature enter its denominator. That makes the rule auditable, but it doesn't make the universe choice for you. Put the exchange list, sector scope and size floor in the thesis. Keep them versioned with the feature definitions. Then a later backtest can replay the whole claim instead of attaching today's ranking population to yesterday's data.
The same warning applies to comparison across runs. If a company's percentile rises, check whether its raw value improved and whether the population moved. A higher rank can come from the company getting better, its peers getting worse, or the evaluable universe changing. The number alone can't tell you which.
How does a combined rank reward balance?
A combined rank merges relative positions on several features into one ordering. The Greenblatt Magic Formula template ranks earnings yield and return on capital separately, then averages the two ranks:
ey_rank:       pct_rank(earnings_yield)
roc_rank:      pct_rank(roc)
combined_rank: (ey_rank + roc_rank) / 2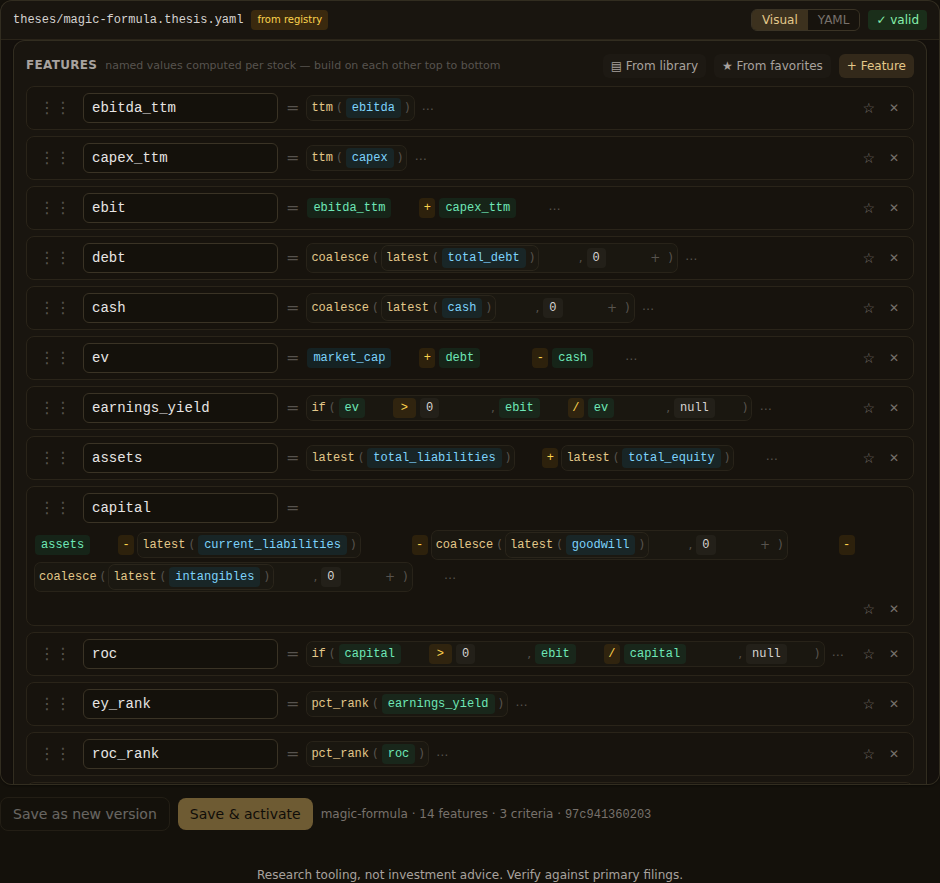
The average rewards balance. A company needs a decent position on both cheapness and operating quality to reach the top of the combined list. A spectacular earnings yield can offset an average return on capital, but only so far. This is better aligned with a "good and cheap" claim than awarding full points for either extreme independently.
Be careful with the word combined. Averaging doesn't create new evidence. If the inputs measure the same underlying fact, the blend just counts one signal twice. Earnings yield and return on capital share an earnings numerator, though their denominators ask different questions. Keep those relationships visible and test what happens when either leg is removed.
Weights are thesis choices as well. An equal average says the two ranks deserve equal influence. Doubling the quality rank says something else. Start with the simple version unless the economic claim gives you a reason to depart from it. A backtest can compare the alternatives, but choosing the prettiest historical curve after trying many weights is still overfitting.
Why should dollar volume stay an absolute gate?
Some facts shouldn't be relative. Dollar volume is price multiplied by average daily share volume, a rough measure of how much stock changes hands in money terms. A percentile rank in dollar volume tells you which names are more liquid than others in your universe. It doesn't tell you whether any of them are liquid enough for the use you have in mind.
A tiny-company universe still has a top decile of liquidity. If the most tradeable name in that pool remains costly to enter and exit, its first-place rank offers no protection. Put an absolute dollar-volume floor in the gate. The threshold will depend on the size and turnover assumptions being tested, so it belongs in a named parameter the reader can change.
The Greenblatt Magic Formula template does exactly this. Its relative combined rank finds the upper tail on quality and valuation. A separate absolute earnings-power rule rejects non-positive operating earnings, and an absolute dollar-volume rule deals with implementability. Relative selection does one job. Minimum requirements do another.
That separation matters in a backtest because reported results are hypothetical and exclude trading costs. Dollar volume isn't a cost model, and it can't estimate the spread or the market impact of a particular order. It prevents the most obvious mismatch between a paper rule and the names it would ask you to trade. A good backtest still needs its other safeguards.
How do you express ranks and thresholds together?
The shape below is illustrative, and the bundled templates plus the Quantery DSL reference are the reference for exact fields. This example ranks return on capital, demands a fixed return floor and keeps the liquidity test absolute. Its syntax was validated in Quantery on the publication date.
# "Relatively strong, absolutely adequate" - illustrative
params:
  roc_floor: 0.12
  rank_strong: 0.90
  rank_ok: 0.70
  min_dollar_volume: 2000000

features:
  ebit_ttm: ttm(operating_income)
  assets_now: newest(total_liabilities) + newest(total_equity)
  current_liabilities_now: newest(current_liabilities)
  goodwill_now: coalesce(newest(goodwill), 0)
  intangibles_now: coalesce(newest(intangibles), 0)
  capital_employed: assets_now - current_liabilities_now
    - goodwill_now - intangibles_now
  roc: if(capital_employed > 0,
    ebit_ttm / capital_employed, null)
  roc_rank: pct_rank(roc)
  dollar_volume: avg_volume * price

criteria:
  relative_quality:
    rules:
      - { when: "is_null(roc_rank)", score: 0, flag: no_rank }
      - { when: "roc_rank >= $rank_strong", score: 2 }
      - { when: "roc_rank >= $rank_ok", score: 1 }
      - { else: 0 }
  absolute_quality:
    rules:
      - { when: "is_null(roc)", score: 0, flag: no_roc }
      - { when: "roc >= $roc_floor", score: 2 }
      - { else: 0 }
  tradeable:
    rules:
      - { when: "is_null(dollar_volume)", score: 0, flag: no_volume }
      - { when: "dollar_volume >= $min_dollar_volume", score: 2 }
      - { else: 0 }

gate:
  mode: strict
The null guards reject a feature when its result is null. They don't require four complete quarters: ttm(operating_income) sums whichever values are available among the newest four quarters and returns null only when all four are missing. If completeness matters to the claim, it needs a separate rule. The strict gate means all three claims must clear their lower rule: good relative standing, adequate economics and adequate liquidity. That may produce no qualifiers in a weak market. Good. An empty result can be the correct result when the absolute claim isn't met.
Now test the structure rather than worshipping one setting. Remove the fixed return floor and see whether the rank admits weak absolute economics in difficult periods. Remove the rank and see whether an easy market floods the result. Change the universe deliberately, then inspect how raw values and ranks move. The rules are yours, including the rules that decide what every company is being compared with.
Research tooling, not investment advice. Nothing here is a recommendation to buy, sell, or hold any security. Screens, scores, and backtests are informational only; backtested results are hypothetical, exclude costs such as commissions and slippage, and do not guarantee future results. Verify against primary filings and make your own decisions.
Want to try this on your own rules? Quantery is free for 14 days: the full app, no card required.
← All articles