How to use AI qualitative scoring
AI qualitative scoring works best as a second pass over companies that have already cleared your quantitative gate. Keep arithmetic, filing values, thresholds, and exclusions in deterministic rules. Give the AI pass the questions that need interpretation, such as whether a claimed moat has observable support or whether capital allocation matches management's language.
In Quantery, that split is explicit. The engine evaluates the quantitative thesis first. If you enable AI scoring and the thesis has qualitative criteria, the configured provider reviews the gate survivors and adds its criterion scores to the quantitative score. You can inspect the prompts, context, notes, and sources instead of treating the model as an invisible ranking machine.
What belongs in the AI pass?
A quantitative criterion should produce the same answer whenever it receives the same inputs. Revenue growth, leverage, free cash flow yield, filing age, and null handling belong there. So do hard exclusions. If missing debt data should disqualify a company, write that policy into the thesis. Don't leave the gap for a model to notice.
A qualitative criterion asks for a judgment that the structured data can't settle by itself. A durable competitive advantage is a useful example. Return on equity may support the case, but it doesn't tell you whether pricing power comes from switching costs, a network effect, regulation, or a temporary shortage. That requires reading evidence and deciding how well it supports the claim.
Write the criterion so the model knows what evidence would change the score. “Is this a good business?” invites a free-form opinion. “Find evidence of pricing power, switching costs, network effects, or a cost position competitors can't readily copy” defines the job. The prompt still requires judgment, but its judgment has boundaries.
The same test works for management. Don't ask whether management is strong. Ask whether recent allocation decisions show disciplined reinvestment, restrained dilution, or acquisitions that fit the stated strategy. Name the behavior. Ask for support. Leave valuation arithmetic in the quantitative layer.
If you're still deciding which parts of an idea can become equations, start with the workflow for building a thesis worth testing. The qualitative pass shouldn't rescue a vague thesis. It should cover the narrow residue that remains after you've made the measurable parts explicit.
How is the AI analyst configured?
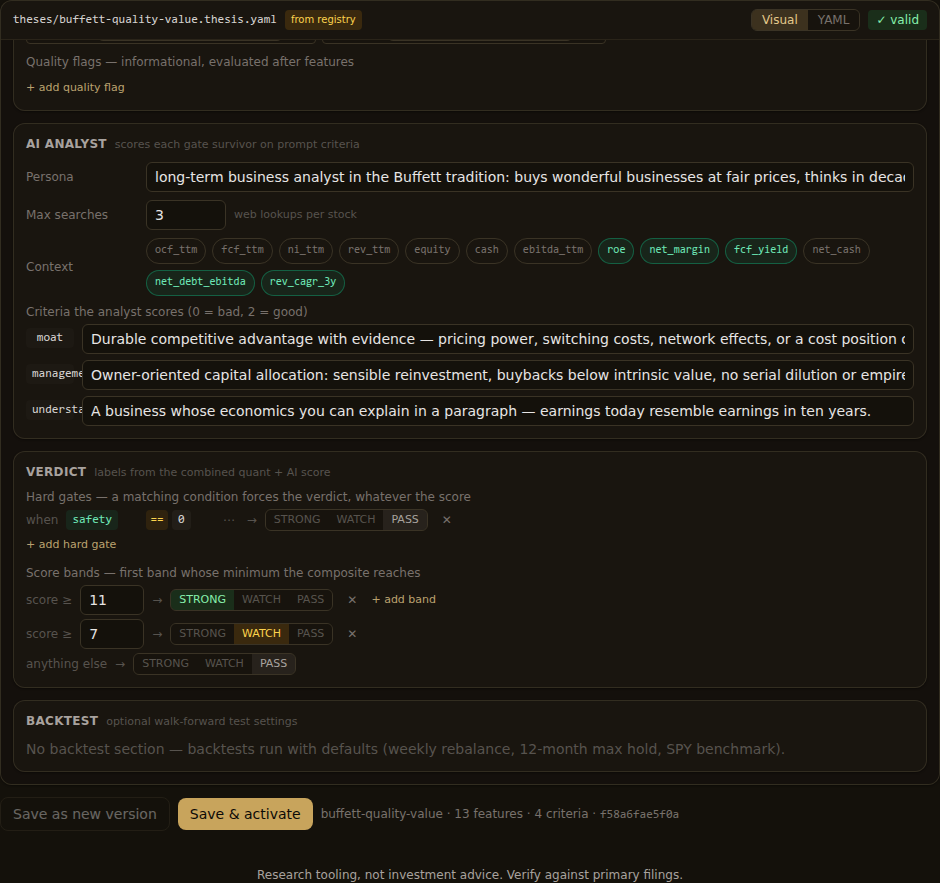
A qualitative section has four moving parts: a persona, a search budget, selected context features, and named prompt criteria. Quantery exposes all four in the thesis builder.
The persona sets the lens. “Long-term business analyst” and “short-horizon event analyst” will attend to different evidence. Keep it specific enough to guide the reading, but don't stuff the answer into the role. A persona should shape the method without guaranteeing a favorable verdict.
The search budget limits web lookups for each company when the provider supports web search. More searches don't automatically produce a better judgment. They create more material to reconcile and more provider usage. Give the model enough room to check the criteria you've written, then tighten the prompts before expanding the budget.
Context features are computed thesis values passed into the prompt. Choose only the values that help interpret the qualitative question. A leverage feature may matter to a capital-allocation review. A valuation rank probably doesn't help the model decide whether customers face switching costs. Irrelevant context encourages a story around numbers that weren't meant to answer the question.
The criteria are the questions the analyst scores. Each one has a stable key and a plain-language prompt. Their scores use the thesis scale. Quantery keeps the precomputed quantitative scores fixed, adds the qualitative scores to form the composite, and then applies any configured verdict rules.
You don't need a qualitative section at all. Without one, gate survivors remain ranked on their quantitative scores. That is often the right starting point because it gives you a baseline before model judgment enters the result.
How do you run the pass without wasting calls?
First, choose an AI provider in settings and use Test connection. Quantery can run a quantitative scan with no provider, so a provider problem shouldn't force you to abandon the deterministic work. If you use a local OpenAI-compatible endpoint, the model has no web search and its verdicts are context-only. Write criteria with that limitation in mind.
Next, open the thesis and read its AI analyst section before running anything. Check that every context feature exists, every criterion asks one researchable question, and the persona fits the time horizon. A prompt inherited from a template is editable. Treat it as a starting point, just like a quantitative threshold.
Run a narrow symbol list or saved watchlist first. Enable AI scoring (qualitative criteria) and set Score cap to a small batch. A cap limits the gate survivors sent to the provider. The unscored survivors still preserve their quantitative result, which lets you inspect the baseline and expand the batch only when the notes are useful.
This order matters because the cap follows the quantitative ranking. The engine sorts gate survivors by their quantitative score, then sends the capped slice through the analyst pass. It isn't a random sample. If you want to evaluate prompt quality across weaker and stronger quantitative cases, build a deliberate symbol list. The capped batch doesn't represent the whole survivor set.
Keep parallel scoring conservative at first. Higher concurrency can run into provider rate limits, while a single local GPU may gain little from several requests at once. Speed is secondary during prompt design. You want to read the first outputs before repeating the same ambiguity across a larger batch.
After the run, compare the scored count with the cap and read any scan errors. A provider limit can stop new scoring calls while preserving the deterministic evaluation. Don't interpret an unscored row as a negative qualitative judgment. It means the analyst result isn't present.
How do you audit an AI verdict?
Start with the separation between facts and judgments. Quantitative feature values come from the thesis evaluator and can be traced through their calculations and stored fundamentals. The stock-screen audit workflow shows how to follow those values to periods, filing dates, and source records.
AI notes are different. They are model judgments over the supplied context and, when available, web research. Quantery retains criterion notes and the source URLs the model reports using. Open those sources. Check whether they support the note. A link in the output proves that a link was returned; it doesn't prove that the interpretation is sound.
Read one criterion at a time. Ask:
- Did the note answer the criterion that was written?
- Is the supporting evidence current enough for the claim?
- Did the model confuse a quantitative feature with qualitative proof?
- Would the same evidence justify the score at the neighboring level?
- Is a missing source or context limit stated in the note?
Then compare companies that received different scores on the same criterion. Score definitions become clearer at their boundaries. If one note earns the highest score and a similar note earns the middle score, the prompt may lack an observable distinction. Rewrite it before treating the composite ranking as informative.
Also read the model's risk flags and highlighted finding as research leads. They aren't established filing facts. Follow the source and check the date. If the provider has no web access, current claims need independent verification outside the model's context.
Changing the model, provider, prompt, context, or search budget changes the research procedure. Record those settings when you compare runs. A composite-score move isn't evidence that the company changed when the analyst setup changed too.
What can the backtest establish?
Quantery backtests the quantitative gate. It doesn't replay the qualitative analyst through history because a present-day model call can't reconstruct the web pages, search results, and judgment available at each old decision date. Feeding today's context into an old date would create look-ahead bias.
That limitation defines a useful division of labor. Use the quantitative thesis as the historical research object. Test whether its point-in-time rules produced a stable result across dates, regimes, and nearby assumptions. Every backtest result is hypothetical and excludes costs. The guide to backtest integrity explains why information availability matters as much as the formula.
Use qualitative scoring as a current research step after that gate. It can help organize evidence around questions the historical engine can't replay. It can't turn an untestable prompt into historical proof, and its composite score shouldn't be described as if it came from the backtest.
This split also gives a failed qualitative prompt somewhere useful to go. If the analyst repeatedly notices a measurable condition, define the measurement. A recurring concern about dilution could become a share-count feature. A recurring claim about cash conversion could become a deterministic criterion. Add it to the quantitative thesis, specify its null policy, and test it through time.
Leave genuinely interpretive questions in the AI layer. Tighten their prompts as you learn where the scores wobble. The goal isn't to automate the last word. It's to keep judgment visible, bounded, and revisable while the arithmetic remains reproducible.
Research tooling, not investment advice. Nothing here is a recommendation to buy, sell, or hold any security. Screens, scores, and backtests are informational only; backtested results are hypothetical, exclude costs such as commissions and slippage, and do not guarantee future results. Verify against primary filings and make your own decisions.
Want to try this on your own rules? Quantery is free for 14 days: the full app, no card required.
← All articles